Research InterestsDiscover my research across three connected themes. 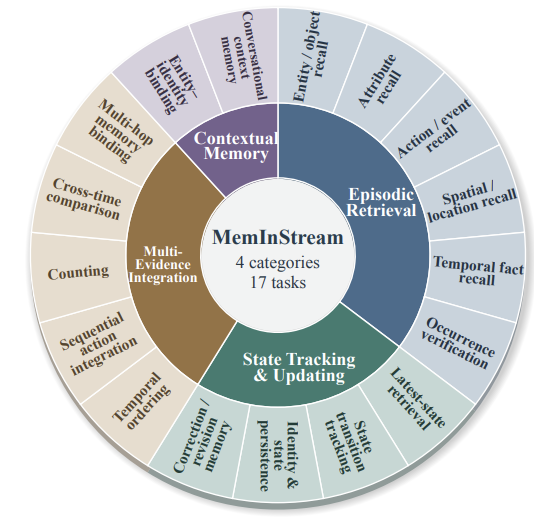 MemInStream: Memorizing or Merely Recognizing? Rethinking Streaming Video Memory Evaluation Zhenqi He, Dunyuan Xu, Yang Bo, Kien T. Pham, Yanghao Wang, Shuhan Li, Xintong Guo, Yuyang He, Fang Liu, Huankang Guan, Jingyan Chen, Rui Liu, Long Chen; Preprint, 2026 [Paper] We introduce MemInStream, a benchmark for streaming video memory. Its evidence-controlled protocol checks that historical evidence is both sufficient and necessary to answer each question, helping separate memory failures from visual understanding errors and memory-independent shortcuts. 
FlowCIR: Semantic Transport via Flow Matching for Zero-Shot Composed Image Retrieval
Zhenqi He, Ziqi Jiang, Yuanpei Liu, Yanghao Wang, Teng Wang, Long Chen; ECCV, 2026 [Paper] In this paper, we are the first to systematically study flow matching for zero-shot composed image retrieval and introduce FlowCIR. 
FlowComposer: Composable Flows for Compositional Zero-Shot Learning
Zhenqi He, Lin Li, Long Chen; CVPR, 2026 [Paper] / [Code] In this paper, we are the first to systematically study flow matching for CZSL and introduce FlowComposer, a model-agnostic framework that learns two primitive flows to transport visual features toward attribute and object text embeddings, and a learnable Composer that explicitly fuses their velocity fields into a composition flow. 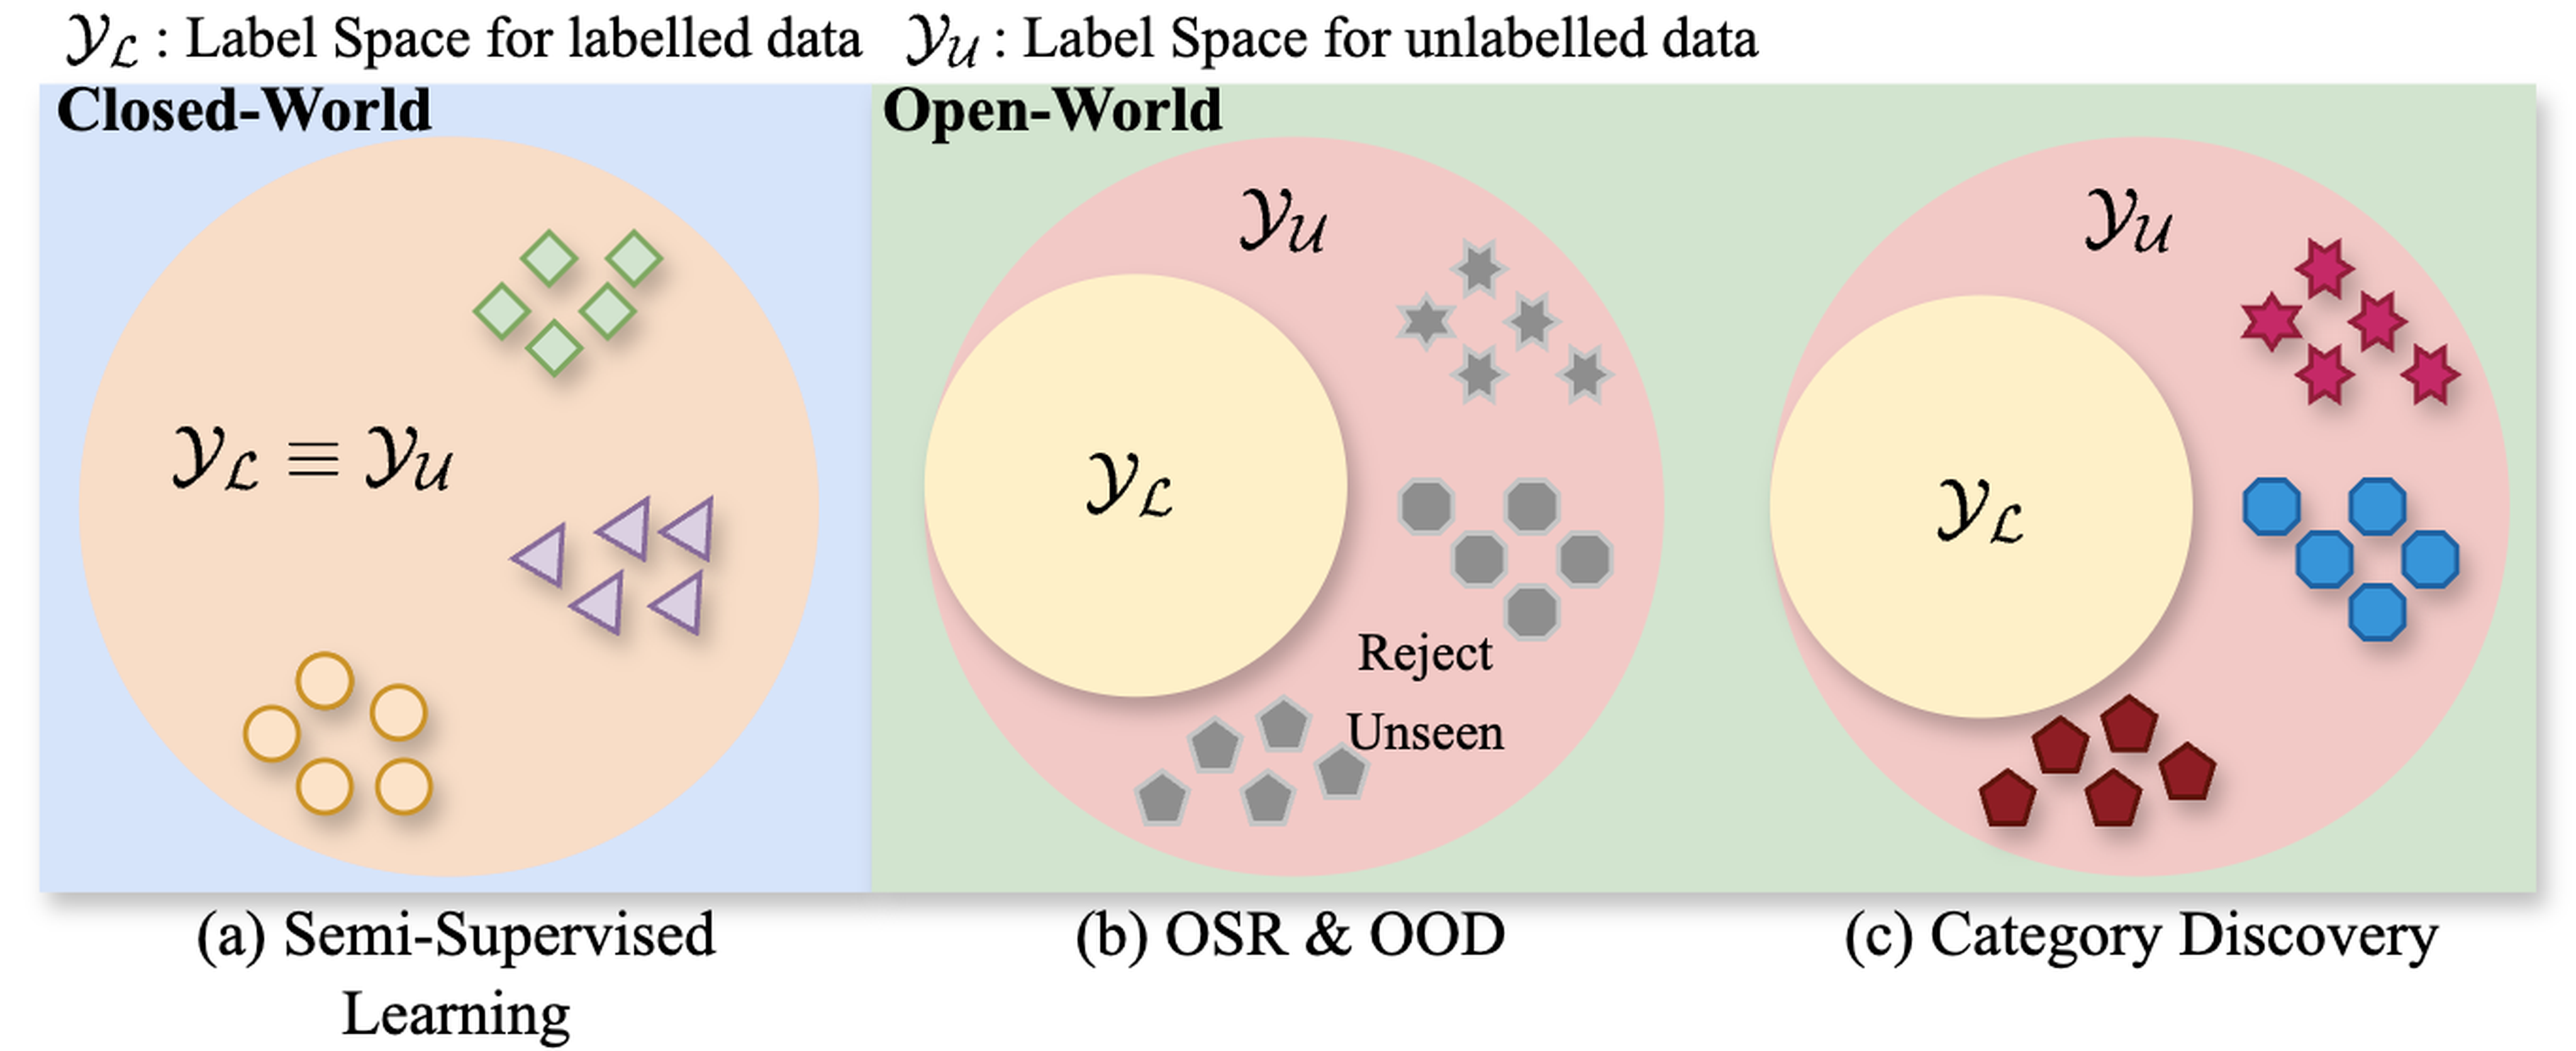
Category Discovery: An Open-World Perspective
Zhenqi He, Yuanpei Liu, Kai Han; Under Review, 2025 [Paper] We survey Category Discovery (CD)—learning to group unlabeled data with potentially unseen classes alongside limited labeled data. We propose a taxonomy spanning NCD, GCD, and real-world variants (continual, long-tailed, federated, etc.), review methods across three core components (representation learning, label assignment, class-number estimation), and provide unified benchmarks. Our analysis shows benefits from large pretrained backbones, hierarchical/auxiliary signals, and curriculum-style training, and surfaces open problems in robust label assignment, reliable class-number estimation, and scaling to complex multi-object scenarios. 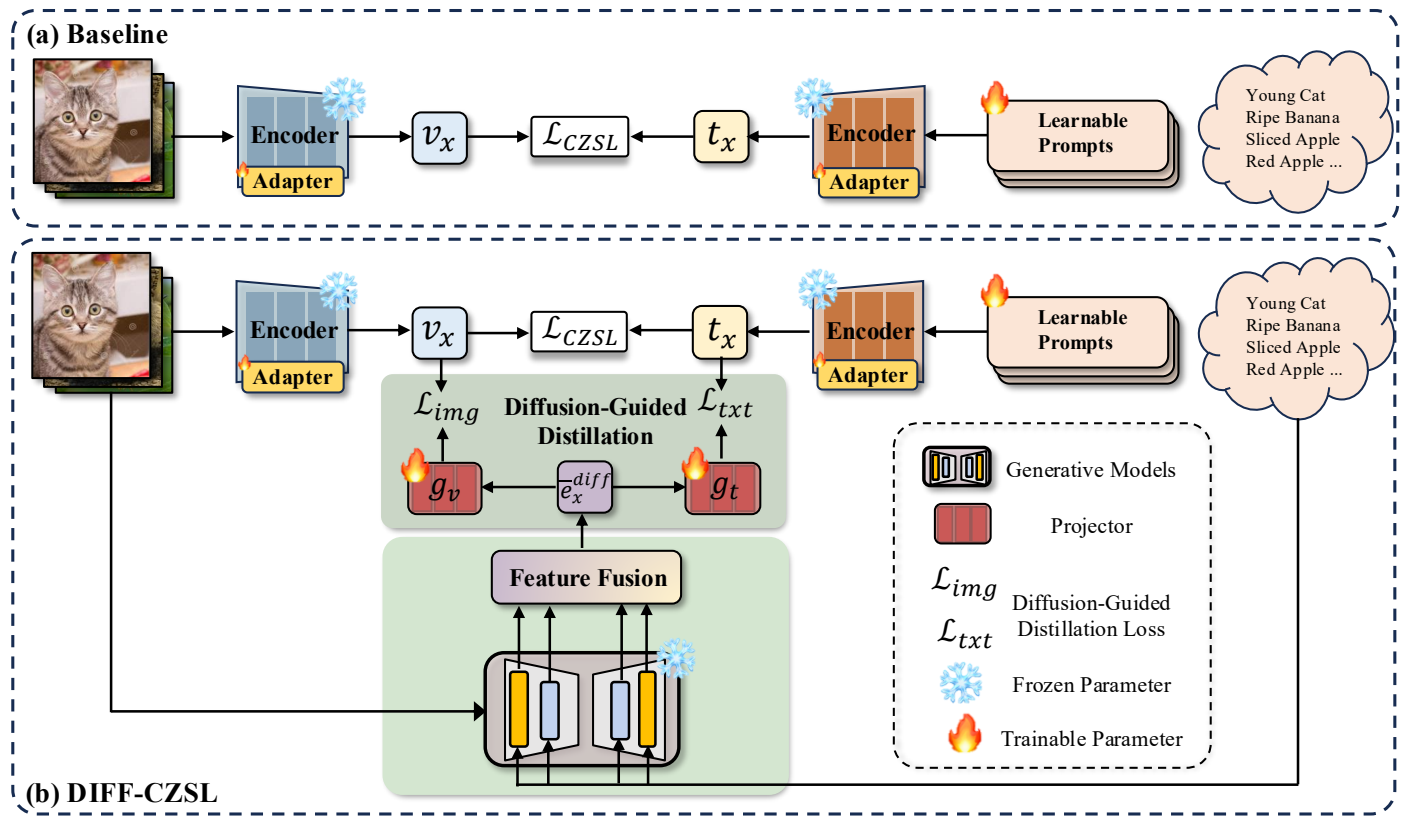
DIFFCZSL: Compositional Zero-Shot Learning Regularized by Diffusion Representations
Hangyu Tian, Zhenqi He†, Yanghao Wang, Long Chen (†: Project Leader); Preprint, 2026 [Paper] We introduce DIFFCZSL, a plug-and-play framework that uses intermediate diffusion representations to regularize CLIP-based compositional zero-shot learning. By aligning diffusion features with both image and text embeddings during training, DIFFCZSL improves compositional generalization without adding inference-time cost. 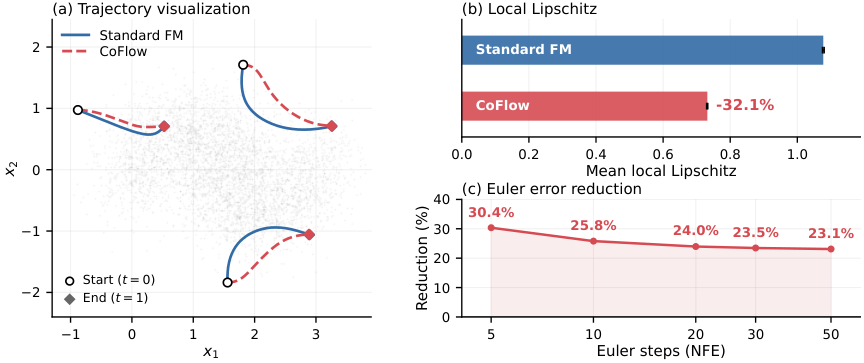 Smoother Flow Matching via Contrastive Trajectory Repulsion
Ziqi Jiang, Zhenqi He, Long Chen; Preprint, 2026 [Paper] / [Code] We introduce CoFlow, a flow matching framework that explicitly repels trajectories during training. By reducing trajectory crossings and smoothing the target velocity field, CoFlow improves image generation with few inference steps. 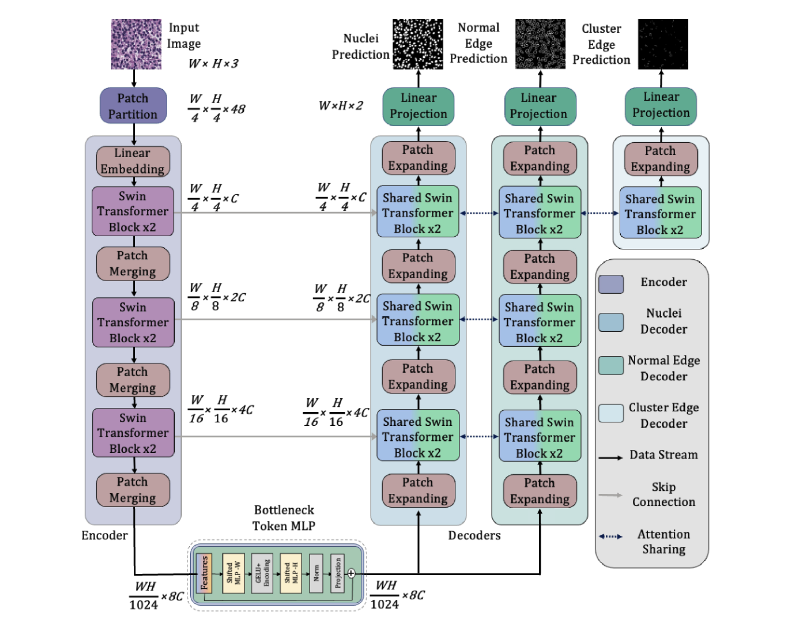
TransNuSeg: A Lightweight Multi-Task Transformer for Nuclei Segmentation
Zhenqi He, Mathias Unberath, Jing Ke, Yiqing Shen; MICCAI, 2023 [Paper] / [Code] This paper proposes a lightweight multi-task framework for nuclei segmentation, namely TransNuSeg, as the first attempt at an entirely Swin-Transformer driven architecture. Innovatively, to alleviate the prediction inconsistency between branches, we propose a self-distillation loss that regulates the consistency between the nuclei decoder and normal edge decoder. And an innovative attention-sharing scheme that shares attention heads amongst all decoders is employed to leverage the high correlation between tasks. 
SEAL: Semantic-Aware Hierarchical Learning for Generalized Category Discovery
Zhenqi He*, Yuanpei Liu*, Kai Han (*: Equal Contribution); NeurIPS, 2025 [Paper] / [Code] We introduce a Semantic-Aware hierArchical Learning framework (SEAL), guided by naturally occurring and easily accessible hierarchical structures. Within SEAL, we propose a Hierarchical Semantic-Guided Soft Contrastive Learning approach that exploits hierarchical similarity to generate informative soft negatives, addressing the limitations of conventional contrastive losses that treat all negatives equally. Furthermore, a Cross-Granularity Consistency (CGC) module is designed to align the predictions from different levels of granularity. 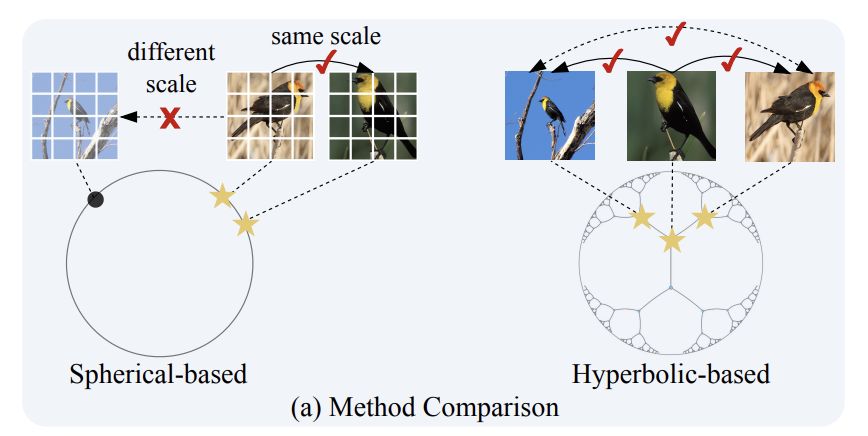
Hyperbolic Category Discovery
Yuanpei Liu*, Zhenqi He*, Kai Han (*: Equal Contribution); CVPR, 2025 [Paper] / [Code] We introduce HypCD, a simple Hyperbolic framework for learning hierarchy-aware representations and classifiers for generalized Category Discovery. HypCD first transforms the Euclidean embedding space of the backbone network into hyperbolic space, facilitating subsequent representation and classification learning by considering both hyperbolic distance and the angle between samples. 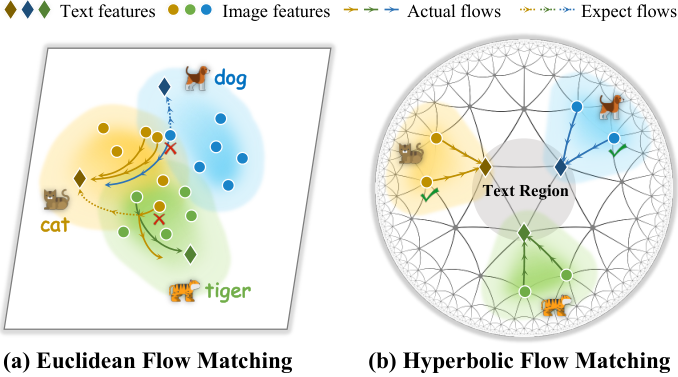 Path-Decoupled Hyperbolic Flow Matching for Few-Shot Adaptation
Lin Li, Ziqi Jiang, Gefan Ye, Zhenqi He, Jiahui Li, Jun Xiao, Kwang-Ting Cheng, Long Chen; Preprint, 2026 [Paper] We propose Hyperbolic Flow Matching for few-shot adaptation. Centripetal hyperbolic alignment and class-specific geodesic corridors separate visual-semantic transport paths, while an adaptive stopping rule prevents over-transportation. 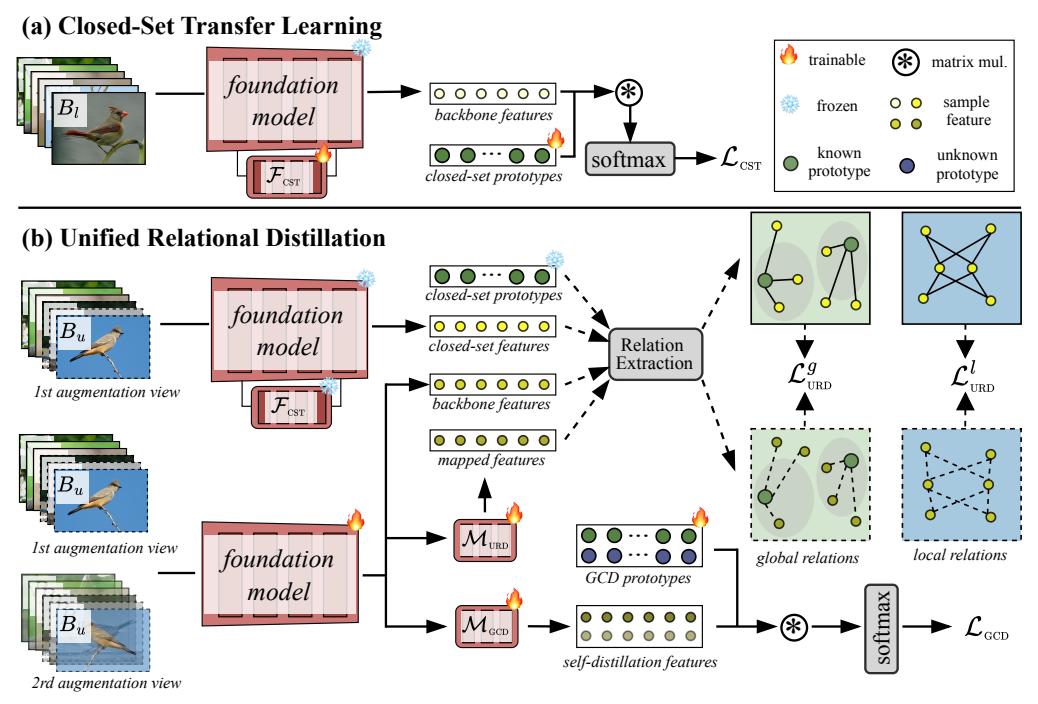
CloSeR: Unified Relational Distillation from Closed-Set Teachers for Category Discovery
Yuanpei Liu, Zhenqi He, Jialu Tang, Kai Han; ECCV, 2026 [Paper] / [Project] We introduce CloSeR, a plug-and-play framework that transfers closed-set relational knowledge to generalized category discovery. A lightweight adapter-based teacher provides global sample-to-prototype and local sample-to-sample relations, which are distilled into the discovery model to preserve semantic structure and improve recognition of known and novel categories. 
Large Language Models are Good Multi-lingual Learners: When LLMs Meet Cross-lingual Prompts
Teng Wang, Zhenqi He, Wing-Yin Yu, Xiaojin Fu, Xiongwei Han; COLING, 2025 [Paper] We introduce a framework integrating MLPrompt with an auto-checking mechanism for structured data generation, with a specific case study in text-toMIP instances. 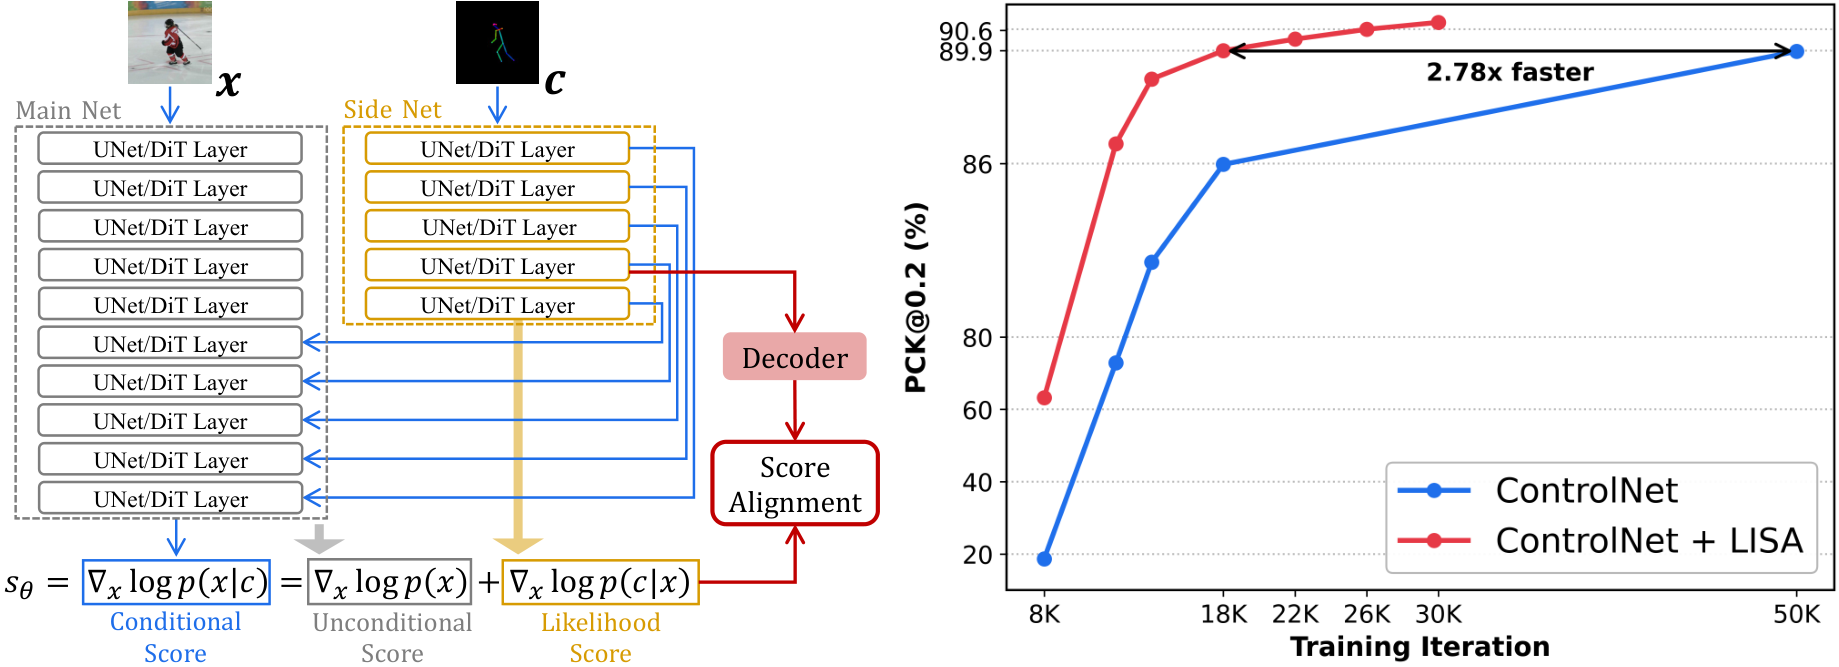 LISA: Likelihood Score Alignment for Visual-condition Controllable Generation
Yanghao Wang, Hongxu Chen, Jiazhen Liu, Zhenqi He, Rui Liu, Zhen Wang, Long Chen; Preprint, 2026 [Paper] / [Code] We introduce LISA, a regularization method for visual-condition controllable generation. Aligning intermediate side-network features with an approximated likelihood score improves training convergence and generation quality without adding inference cost.  AURA 2.0: From User-Driven Responses to Model-Initiated Conversations in Streaming Video Shuhan Li, Huankang Guan, Xintong Guo, Yang Bo, Yuyang He, Dunyuan Xu, Jingyan Chen, Fang Liu, Tsz Kin Wan, Jinpeng Chen, Zhenqi He, Yuxuan Hu, Wenbo Li, Han Gao, Qijun Li, Long Chen, Hongsheng Li, Rui Liu; Preprint, 2026 [Paper] We present a streaming video language model that initiates conversations, calls tools using streaming context, and grounds interactions in video frames. Long-horizon interaction memory maintains continuity across extended video streams. 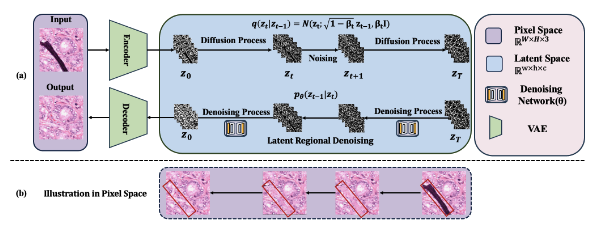
Latent ArtiFusion: a Effective and Efficient Histological Artifacts Restoration Framework
Zhenqi He, Wenrui Liu, Minghao Yin, Kai Han; DGM4MICCAI, 2024 [Paper] / [Code] In this paper, we propose a novel framework, namely LatentArtiFusion, which leverages the latent diffusion model (LDM) to reconstruct histological artifacts with high performance and computational efficiency. Unlike traditional pixel-level diffusion frameworks, LatentArtiFusion executes the restoration process in a lower-dimensional latent space, significantly improving computational efficiency. Through extensive experiments on real-world histology datasets, LatentArtiFusion demonstrates remarkable speed, outperforming state-of-the-art pixel-level diffusion frameworks by more than 30×. 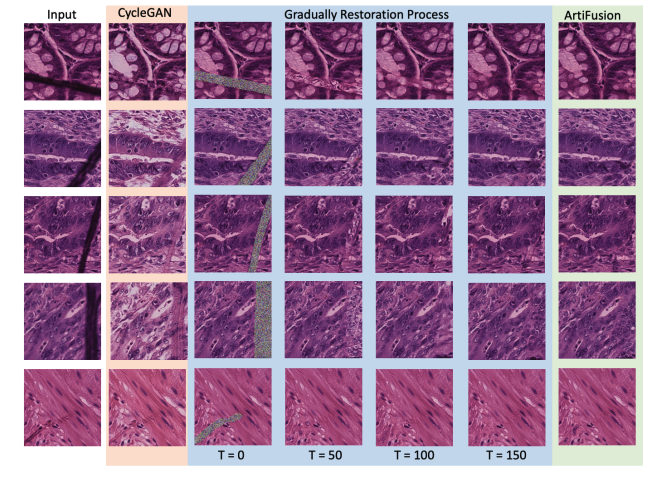
Artifact Restoration in Histology Images with Diffusion Probabilistic Models
Zhenqi He, Junjun He, Jin Ye, Yiqing Shen; MICCAI, 2023 [Paper] / [Code] This is the first attempt at a denoising diffusion probabilistic model for histological artifact restoration, called ArtiFusion. Specifically, ArtiFusion formulates the artifact region restoration as a gradual denoising process, and its training relies solely on artifact-free images to simplify the training complexity. Furthermore, to capture local-global correlations in the regional artifact restoration, a novel Swin-Transformer denoising architecture is designed, along with a time token scheme. Our extensive evaluations demonstrate the effectiveness of ArtiFusion as a pre-processing method for histology analysis, which can successfully preserve the tissue structures and stain style in artifact-free regions during the restoration. 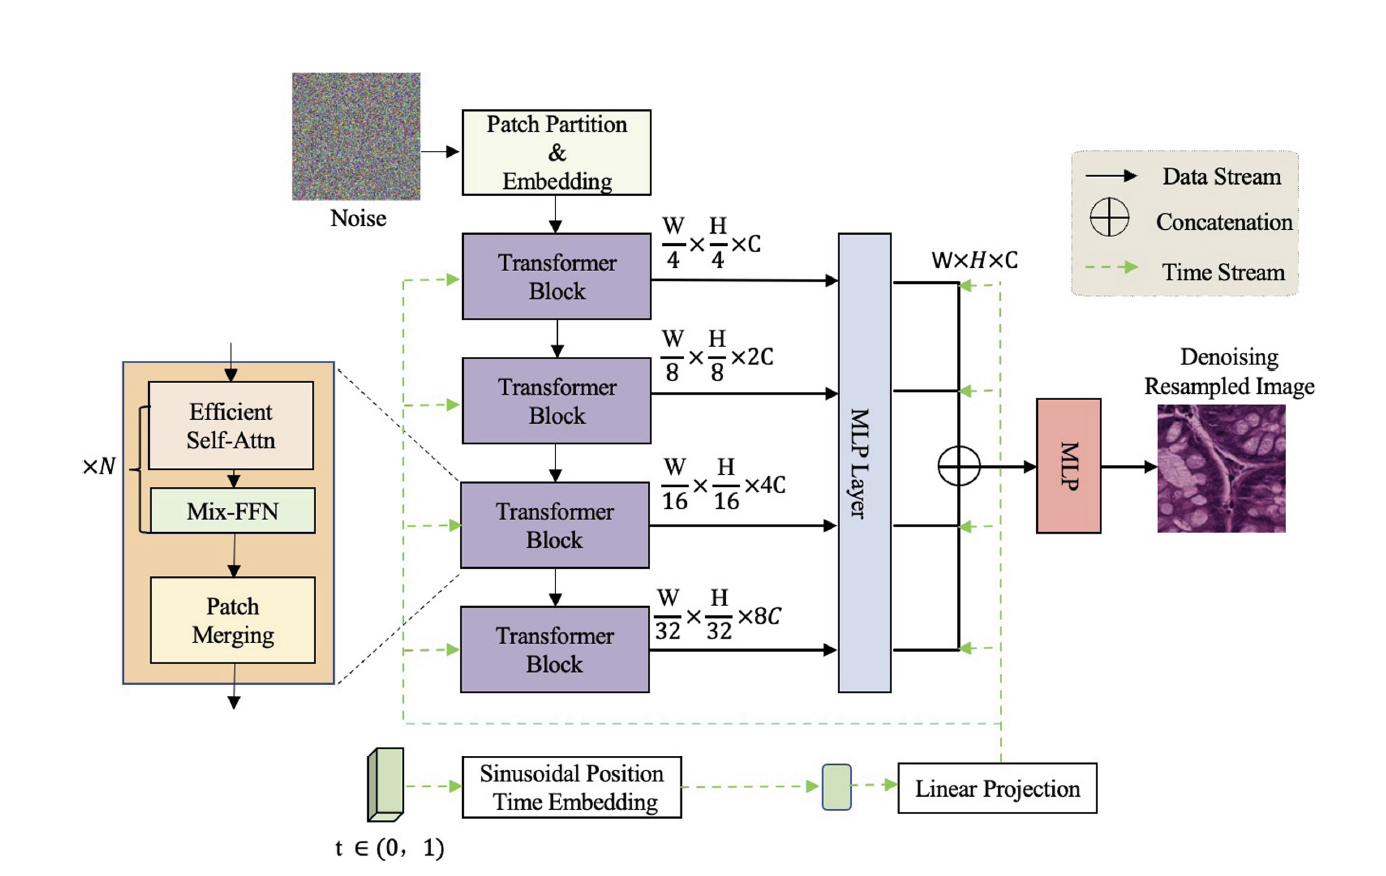
Histology Image Artifact Restoration with Lightweight Transformer and Diffusion Model
Chong Wang, Zhenqi He, Junjun He, Jin Ye, Yiqing Shen; AIME, 2024 [Paper] / [Code] In this paper, we propose a lightweight transformer based framework for histological artifacts restoration. In comparison to existing generative adversarial network (GAN) based solutions, our method minimizes changes in morphology while maximizing preservation of the stain style during the restoration of the artifact. By providing a more reliable and accurate restoration of artifact-affected areas, our model facilitates better analysis and interpretation of histological images, thereby potentially improving the accuracy of tumor diagnosis and treatment decisions.
|
Education
|
Ph.D. in Computer Science and Engineering HKUST, Clear Water Bay 2025 - 2029 Advisor: Prof. Long Chen |
|
MSc. in Artificial Intelligence The University of Hong Kong, Hong Kong Sep. 2023 - Jan. 2025 Advisor: Prof. Kai Han Grade: Distinction |
|
|
BSc in Mathematics (Double Major in Computer Science) The University of Hong Kong, Hong Kong Sep. 2018 - Jun. 2023 |
Experiences
|
Research Intern Hong Kong Observatory, Hong Kong Jan. 2022 – Jan. 2023 |
|
This page is build on source code |